Published September 22, 2026
How to Test an AI Prompt: A Practical V1 to V2 Prompt Testing Framework
A good AI result once does not prove that a prompt is reliable. Learn how to test prompts with schema validation, semantic correctness, and structured test cases.
On This Page
- What Is Prompt Testing?
- Why Is One Good AI Response Not Enough?
- The V1 → Test → V2 Prompt Testing Workflow
- Step 1: Start With a V1 Prompt
- Step 2: Define What a Successful Result Looks Like
- Step 3: Build a Prompt Test Dataset
- Cohesive Practical Example: Product Extraction with JSON Schema
- Step 4: Record Results & Classify Errors
- Step 5: Develop V2 and Address Root Causes
- Step 6: Re-test, Measure Improvement, & Regression Testing
- Conclusion: Towards Automated LLM Evaluation
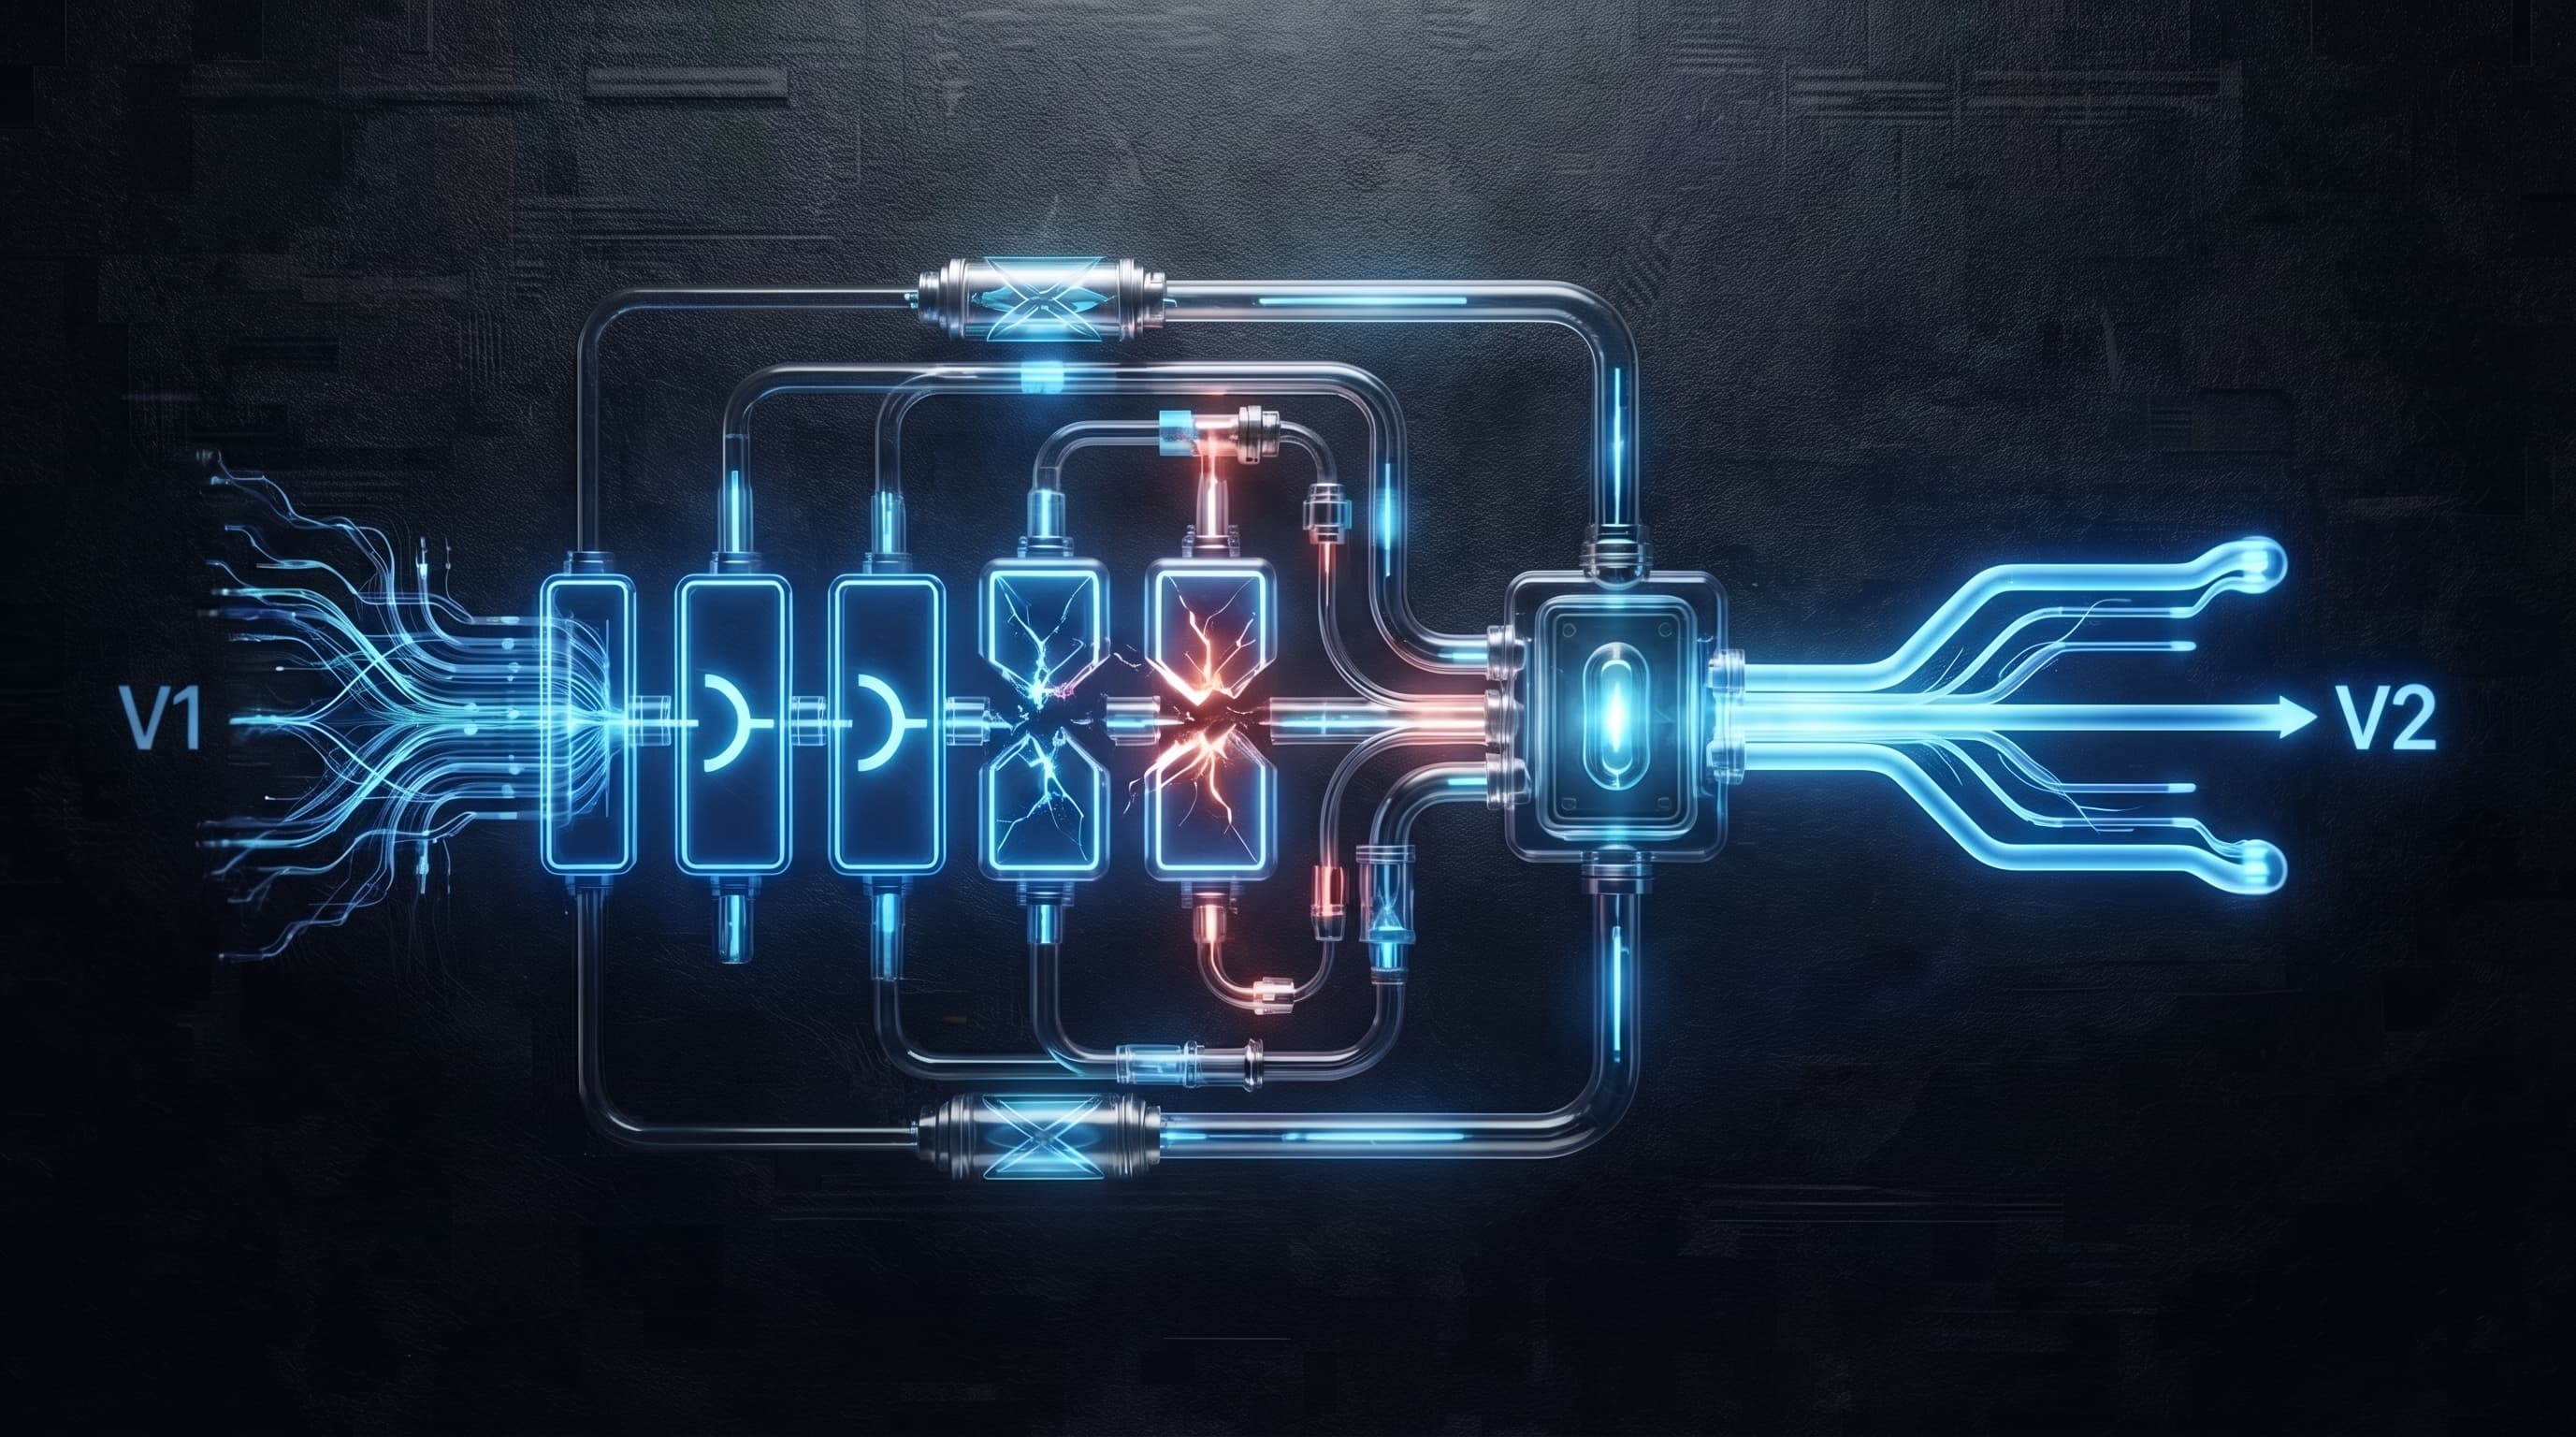
Writing a good prompt is not the end of prompt engineering; it is the beginning of testing. A prompt may produce an excellent result for one example and then fail when the input changes or an unexpected case appears. The better question is not, “Did the AI give me a good answer?” but, “Does this prompt produce the expected behavior across a meaningful set of test cases?” In this guide, we will turn prompt testing into a repeatable workflow: V1 → success criteria → test cases → results → error analysis → V2 → re-test → comparison.
What Is Prompt Testing?
Prompt testing is the process of running a prompt against a test dataset and comparing the outputs with predefined success criteria. The goal is not to obtain one impressive answer, but to determine whether the prompt behaves predictably across normal, difficult, and unusual cases.
Prompt testing does not mean asking the model once, liking the answer, and declaring the prompt successful. A single result may not reveal consistency problems, edge cases, formatting failures, or weaknesses that appear with different inputs.
Why Is One Good AI Response Not Enough?
A simple input can hide weaknesses in the instructions. A prompt may work with a short text but fail with a longer one, or work when all information is present but fail when a value is missing. A change that fixes one case can also affect another case. This is why prompt improvement requires repeated testing rather than relying on subjective impressions.
The V1 → Test → V2 Prompt Testing Workflow
Prompt testing can be treated as a small development cycle. Start with V1, define what success means, create a test dataset, run the prompt, record the results, identify errors and their likely causes, and then create V2 to address the observed problems. Finally, run the same test cases again and compare the two versions.
V1 → Define success criteria → Build test dataset → Run tests → Record results → Analyze errors → Create V2 → Re-test → Compare
Step 1: Start With a V1 Prompt
Do not try to create the perfect prompt before testing it. The purpose of V1 is to establish a baseline that can be measured. If you rewrite the prompt repeatedly before recording results, it becomes difficult to know which change actually improved the behavior.
Extract the product name, price, category, and availability from the following text.
This prompt is usable, but it does not define how to handle missing values, multiple products, or the required output structure. (Basic definition: A test case is an individual scenario containing input and expected behavior, while a test dataset is the organized collection of these scenarios).
Step 2: Define What a Successful Result Looks Like
When evaluating outputs, especially in advanced prompts or structured outputs, we must carefully distinguish between the following technical quality criteria:
| Criterion | Question to Test |
|---|---|
| Syntax | Is the output syntactically valid (e.g., valid JSON without malformed syntax)? |
| Schema compliance | Does the output strictly adhere to the defined fields and types in the schema? |
| Source-groundedness | Is the output fully supported by the input text without unsupported inventions? |
| Semantic & Factual correctness | Semantic: does output reflect requested meaning? Factual: is info correct against external sources when required? |
| Consistency | Does the prompt produce stable results when repeated under controlled model settings? |
Step 3: Build a Prompt Test Dataset
The appropriate test cases vary depending on the task nature, whether extraction, summarization, classification, or code generation. To ensure thorough coverage, we typically start with five core categories in our test dataset:
| Test Case Category | Purpose |
|---|---|
| Normal case | Represents the most common use of the prompt. |
| Simple case | Checks whether the prompt handles the basic task without unnecessary complexity. |
| Complex case | Tests the prompt with more information or more demanding requirements. |
| Edge case | Tests an unusual input that is still valid within system boundaries. |
| Failure-prone case | Intentionally targets a known or suspected weakness. |
Cohesive Practical Example: Product Extraction with JSON Schema
Suppose we require structured outputs matching the following JSON Schema... We will apply five test cases to evaluate V1:
| Test | Dataset Input | Expected Behavior |
|---|---|---|
| T1 - Normal | Apple iPhone 15, Smartphones category, 128GB, $699. Available now. | Extract all four fields accurately matching source facts. |
| T2 - Missing value | Apple iPhone 15, Smartphones category, 128GB. Currently available. | Return null for price without inventing anything. |
| T3 - Multiple products | iPhone 15 — $699. Samsung Galaxy S25 — $799. | Handle both products as two separate items inside the products array. |
| T4 - Ambiguous availability | iPhone 15 is listed, but stock info is uncertain. | Return availability: null due to lack of explicit confirmation. |
| T5 - Irrelevant input | Contact our sales department for information about our latest smartphones. | Do not invent a product or price not present in the input. |
Step 4: Record Results & Classify Errors
After running V1, we record results and categorize errors. The following table illustrates V1 results and observed errors:
| Test | Illustrative V1 Result | Status | Main Error Type |
|---|---|---|---|
| T1 | Extracted basic data successfully | Pass | — |
| T2 | Invented a price not in the text | Fail | Source-groundedness failure |
| T3 | Merged products ignoring schema | Fail | Schema structural error (Multiple Products) |
| T4 | Treated ambiguity as confirmed availability | Fail | Semantic error |
| T5 | Invented dummy product from sales text | Fail | Hallucination / out-of-context |
Step 5: Develop V2 and Address Root Causes
Based on observed errors, we revise the prompt to target root causes instead of relying on vague instructions. Here is the revised V2 prompt:
Extract product name, price, category, and availability exclusively in JSON matching the defined schema.

Strict Rules:
- Use only info stated in input (Source-groundedness).
- If any value is missing, output null and do not guess.
- If multiple products exist, create a separate object for each inside the products array.
- Do not add any fields outside the schema (additionalProperties: false).
- Do not mark a product as available unless explicitly stated.
Step 6: Re-test, Measure Improvement, & Regression Testing
To quantitatively evaluate performance, we use clear mathematical metrics like Pass Rate and Schema Compliance Rate...
| Performance Metric | Version V1 (Illustrative) | Version V2 (Illustrative) |
|---|---|---|
| Overall Pass Rate | 20% (1/5 passed) | 100% (5/5 passed) |
| Schema Compliance | 60% (3/5 compliant) | 100% (5/5 compliant) |
| Data Hallucination Rate within Dataset | High (4 errors in dataset) | Zero (0/5 cases in dataset) |
How to make testing reproducible? Fix model version and generation settings, use the same test dataset, document prompt versions, and always run full regression testing to prevent overfitting.
Conclusion: Towards Automated LLM Evaluation
A good prompt is not the one that succeeds in a single case, but one whose behavior you can measure, debug, improve, and re-test with confidence. As your applications scale, you will naturally transition from manual testing to automated evaluation and evaluation datasets.
Read also
ChatGPT JSON Output: How to Get Structured, Reliable JSON Responses
A practical guide to prompting ChatGPT for reliable structured JSON output, with schema design, JSON Mode, Structured Outputs, common mistakes, and ready-to-copy templates.
How to Write a Professional AI Prompt: Complete Prompt Engineering Guide
A practical comprehensive guide to writing effective AI prompts. Learn how to structure clear instructions, use zero-shot, one-shot and few-shot prompting, break down complex tasks with prompt chaining, and apply professional prompt templates to real-world tasks.

Negative Prompting Beyond Images: How to Tell Any AI Tool What Not to Do
Negative prompting is well known in image generation for naming what to exclude. The same idea works more effectively than many expect in text, code, and even AI agents.